AI Training Opt Out Robots.txt: 6 Easy Templates + India Data
The AI training opt out in robots.txt is two lines: User-Agent: __usage_ai-training and Disallow: /. Google, Microsoft, OpenAI and Anthropic agreed to honour this one shared rule on October 30, 2026. Microsoft starts on February 1, 2027, Google in early 2027, OpenAI in the coming months, and Anthropic has started building support. It does not stop crawling and does not change Google or Bing rankings. In Peplio’s study of Indian websites, not one of the 230 sites with a readable robots.txt uses it yet. Use the free checker and builder below to set yours in five minutes.
__usage_ai-training.ai-training:disallow and ai-grounding:disallow. NoArchive and NoCache stop counting as AI signals on March 1, 2027.__usage_ai-training, so one robots.txt group can carry your training choice to all of them. Sources: PPC Land, ShiftDelete- What the AI training opt out in robots.txt is
- Indian data: how 230 sites handle AI crawlers today
- Training bots vs AI search bots (the mistake to avoid)
- Free checker: read your robots.txt
- Free builder: write your AI rules
- 6 ready templates by website type
- 9-step setup checklist
- Free Excel planner and PDF templates
- Token vs Google-Extended vs Bing tags vs llms.txt
- FAQ
What Is the AI Training Opt Out in Robots.txt?
Until October 2026, saying no to AI training meant writing a separate rule for every company: GPTBot for OpenAI, ClaudeBot for Anthropic, Google-Extended for Google, and so on. The new AI training opt out in robots.txt replaces that with one shared name,__usage_ai-training. You write it where a crawler name normally goes, then add normal Allow and Disallow lines.User-Agent: __usage_ai-training Disallow: /| Question | Answer |
|---|---|
| Does it stop bots visiting my site? | No. The draft says it “is not a directive for crawling behavior” |
| Does it change Google or Bing rankings? | No. Microsoft: “The traditional Bing rankings are unaffected”. Google-Extended does not affect Google Search |
Does User-Agent: * count? | No. A wildcard group never carries a training preference. You must name the token |
| Is it case-sensitive? | No. Matching ignores case |
| Can I opt out some folders only? | Yes. Use Disallow: /courses/ for one folder, or Disallow: / plus Allow: /press-kit/ to share a few |
| Does it affect AI answers that cite me? | It covers training. But for Google, a token opt-out counts as a Google-Extended block, which can also remove you from Gemini Apps grounding |
| Is it an official standard? | Not yet. It is an IETF draft that expires May 3, 2027 unless revised |
Sources: Relevant Audience, PPC Land, Digidai
Indian Data: How 230 Websites Handle AI Training Today
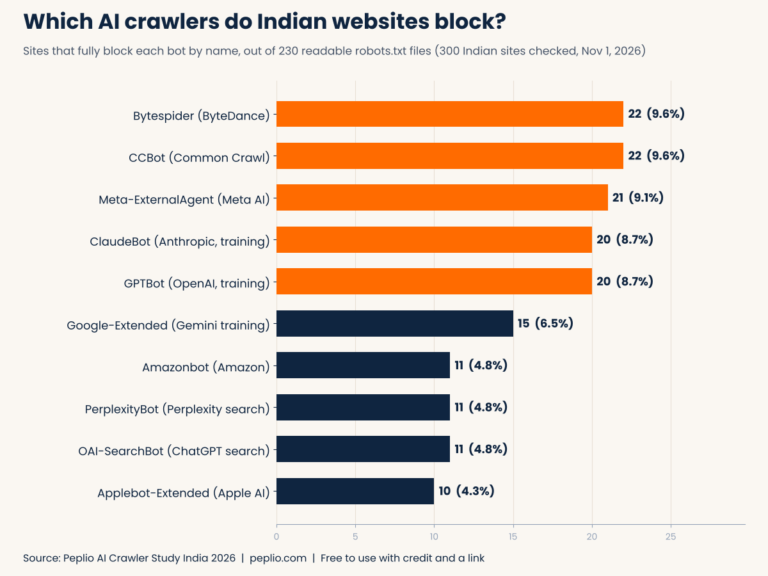
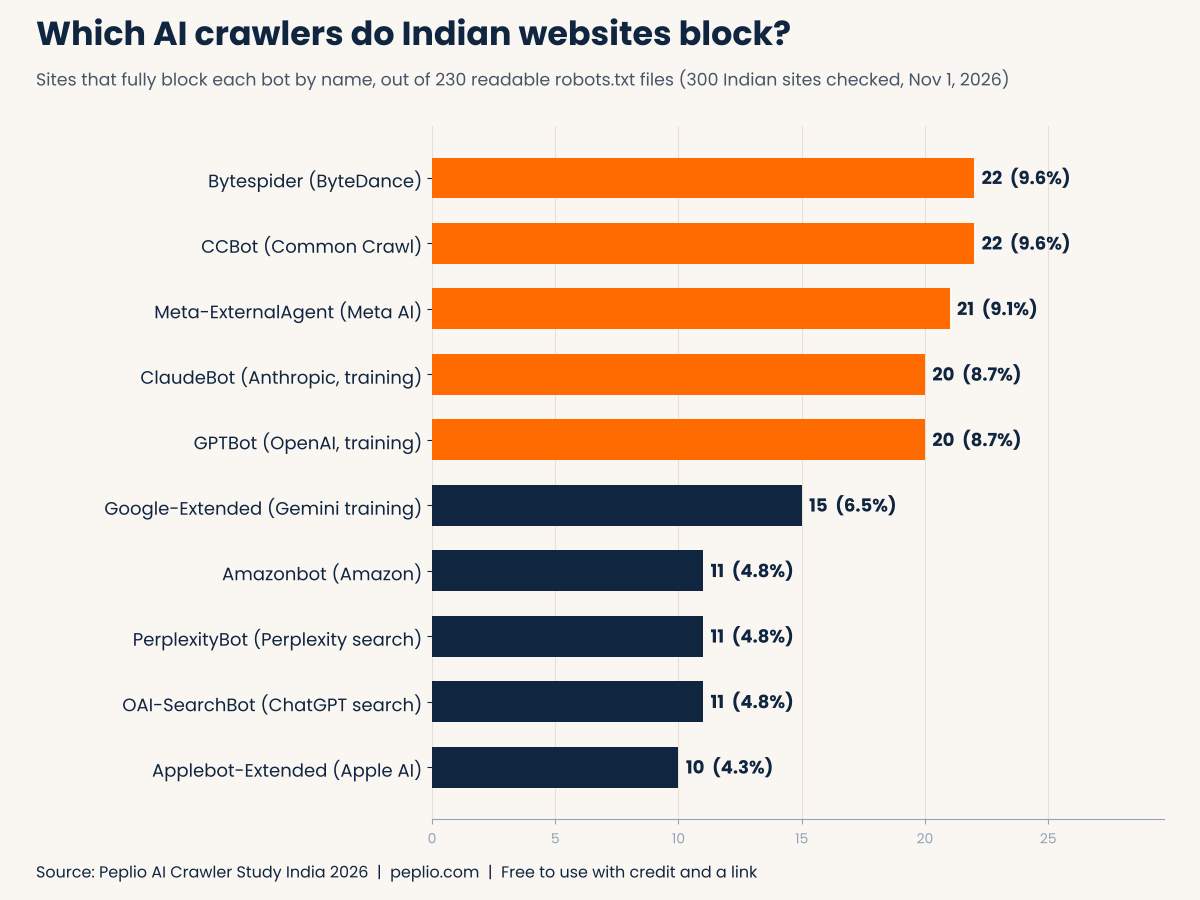
On November 1, 2026, Peplio checked the robots.txt files of 300 well-known Indian websites, 50 in each of six sectors. 230 had a file we could read. Here is how many fully block each AI crawler by name. Read the full method in the Indian websites AI crawler study.| Crawler or token | Company | What it does | Sites fully blocking it (of 230) |
|---|---|---|---|
| __usage_ai-training | Shared | New AI training preference | 0 (0%) use it at all |
| CCBot | Common Crawl | Open web archive used in many AI training sets | 22 (9.6%) |
| Bytespider | ByteDance | Crawler reported for AI training | 22 (9.6%) |
| meta-externalagent | Meta | AI training | 21 (9.1%) |
| GPTBot | OpenAI | AI training | 20 (8.7%) |
| ClaudeBot | Anthropic | AI training | 20 (8.7%) |
| Google-Extended | Gemini training and grounding | 15 (6.5%) | |
| OAI-SearchBot | OpenAI | ChatGPT search | 11 (4.8%) |
| PerplexityBot | Perplexity | Perplexity search | 11 (4.8%) |
| Amazonbot | Amazon | Amazon products and AI | 11 (4.8%) |
| Applebot-Extended | Apple | Apple AI training | 10 (4.3%) |
Source: Peplio AI crawler study, robots.txt files read on November 1, 2026. Full block means Disallow: / for that crawler.
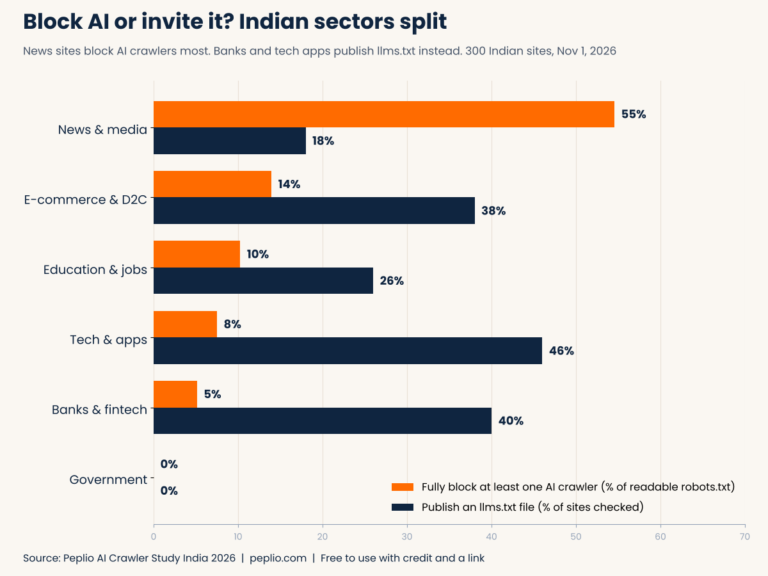
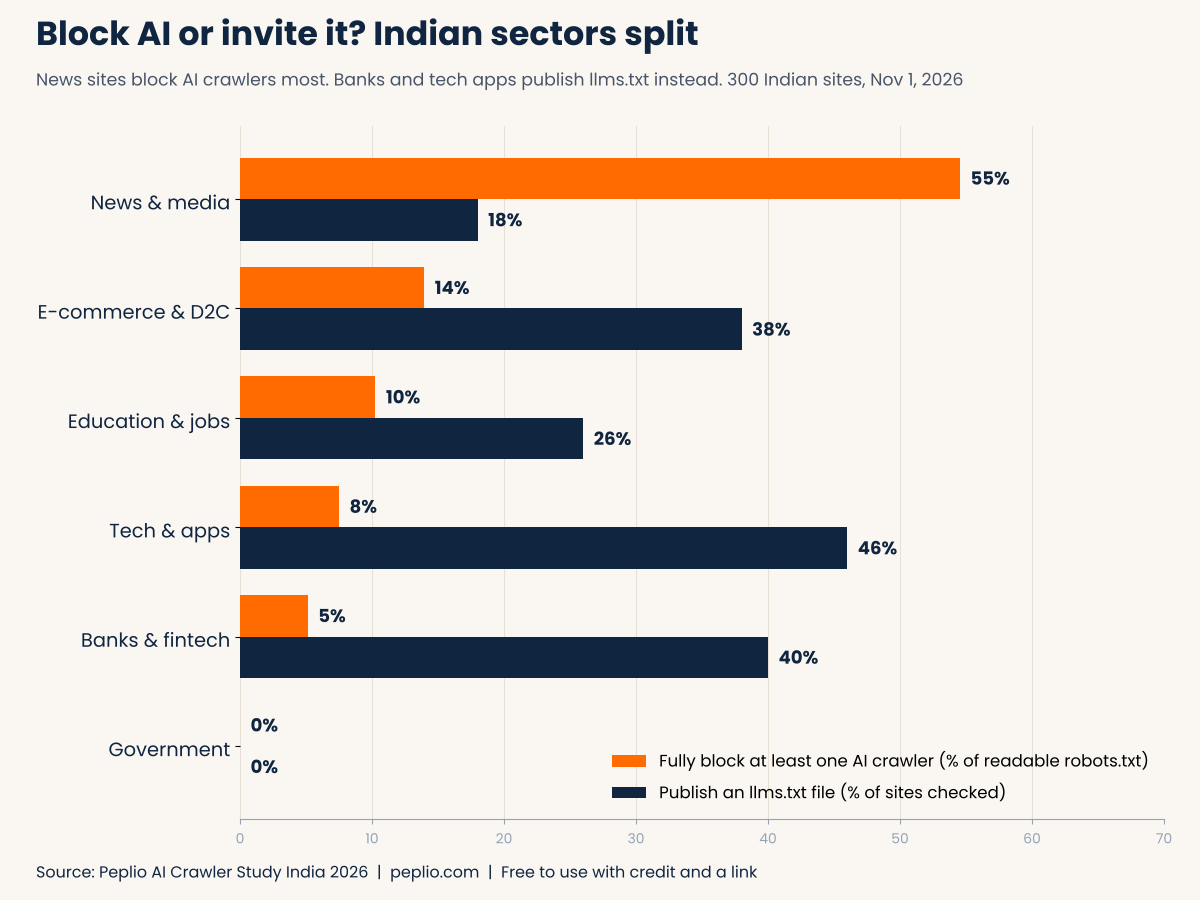
- News sites lead. 24 of 44 news and media sites (55%) fully block at least one AI crawler. In every other sector it is under 15%, and government sites block none.
- Some sites block AI search by mistake. 11 sites block OAI-SearchBot, the bot that powers ChatGPT search, not training. If the goal was to stop training, those sites lost ChatGPT search visibility for nothing.
- Nobody uses the new token yet. Every site that blocks AI training today does it bot by bot. Those lists go out of date as new bots appear. The shared token is the cleaner way forward.
| Sector | Readable robots.txt | Fully block 1+ AI crawler | Block GPTBot | Have llms.txt |
|---|---|---|---|---|
| News and media | 44 | 24 (55%) | 14 | 9 |
| E-commerce and D2C brands | 43 | 6 (14%) | 4 | 19 |
| Education, edtech and jobs | 39 | 4 (10%) | 2 | 13 |
| Tech, travel and consumer apps | 40 | 3 (8%) | 0 | 23 |
| Banks, fintech and insurance | 39 | 2 (5%) | 0 | 20 |
| Government and public bodies | 25 | 0 (0%) | 0 | 0 |
Training Bots vs AI Search Bots: The Mistake to Avoid
This is the most important part of any AI training opt out in robots.txt. Some AI bots collect pages to train models. Others fetch pages to answer a question right now and link back to you. Block a training bot and you lose nothing in search. Block a search bot and you disappear from that AI’s answers.| Company | Training (safe to opt out) | AI search and answers (keep open for visibility) | Normal search (never block) |
|---|---|---|---|
| OpenAI | GPTBot | OAI-SearchBot, ChatGPT-User | none |
| Anthropic | ClaudeBot | Claude-SearchBot, Claude-User | none |
| Google-Extended (also Gemini Apps grounding) | AI Overviews and AI Mode use Googlebot | Googlebot | |
| Microsoft | Shared token or ai-training:disallow tag | ai-grounding tag controls Copilot answers | Bingbot |
| Perplexity | none named | PerplexityBot, Perplexity-User | none |
| Others | CCBot, meta-externalagent, Applebot-Extended, Bytespider | Amazonbot (mixed use) | none |
Sources: Search Engine Journal AI crawler list, Search Engine Roundtable, The Back Room Tech
Google is the tricky one. AI Overviews and AI Mode in Google Search use the normal Googlebot, so you cannot opt out of them with robots.txt without leaving Google Search. Google-Extended only covers Gemini training and Gemini Apps grounding.Free AI Training Opt Out Robots.txt Checker
Open yoursite.com/robots.txt in your browser, copy everything, and paste it below. The checker reads it the way AI companies do and shows, bot by bot, what your file says today. Nothing is uploaded: it runs in your browser.The sample is a typical file we saw in the Indian study. The checker follows the robots.txt rules (named group first, then User-agent: *), and never applies * to the training token.
Need a clean robots.txt and sitemap from scratch? Make both free in a minute.
Free AI Training Opt Out Robots.txt Builder
Pick your type of website. The builder suggests the right choice, and you can change any setting. Copy the result and paste it at the top of your robots.txt, above your normal rules.The builder never adds rules for Googlebot, Bingbot or AI search bots, so your search visibility stays safe.
6 Ready AI Training Opt Out Robots.txt Templates
Prefer copy and paste? Pick the template closest to your site and change the folder names. All six are also in the free PDF below, with notes on each.1. Blog or content site: say yes clearly
User-Agent: __usage_ai-training Allow: /2. News publisher: opt out of training, stay in AI search
User-Agent: __usage_ai-training Disallow: / User-Agent: Google-Extended Disallow: / User-Agent: GPTBot Disallow: / User-Agent: ClaudeBot Disallow: / User-Agent: CCBot Disallow: /3. Online store: allow training, keep private pages out
User-Agent: __usage_ai-training Allow: / Disallow: /account/ Disallow: /checkout/4. Business or SaaS: allow training, keep Gemini grounding
User-Agent: __usage_ai-training Allow: / User-Agent: Google-Extended Allow: /5. Paid courses or research: opt out the paid folders only
User-Agent: __usage_ai-training Disallow: /courses/ Disallow: /members/6. Artist or photographer: opt out everything except your press kit
User-Agent: __usage_ai-training Disallow: / Allow: /about/ Allow: /press-kit/ User-Agent: meta-externalagent Disallow: / User-Agent: Bytespider Disallow: / User-Agent: Applebot-Extended Disallow: /How to Set Up an AI Training Opt Out in Robots.txt: 9 Steps
Tick each step as you finish it. Your progress saves in your browser, so you can close the page and come back.- Save a dated copy of your current robots.txt (yoursite.com/robots.txt).
- Run the checker above and note every AI bot your file already blocks.
- Unblock AI search bots you blocked by mistake (OAI-SearchBot, Claude-SearchBot, PerplexityBot), unless you really want out of AI answers.
- Decide your training choice: allow, opt out, or opt out some folders. The builder suggests one for your site type.
- Decide Google-Extended on purpose, because a token opt-out alone also counts as a Google-Extended block.
- Build your lines with the builder or a template, and keep GPTBot and ClaudeBot rules until OpenAI and Anthropic confirm support.
- Publish the file. In WordPress, use the robots.txt editor in Rank Math or Yoast, or upload the file to your site root.
- Test it: open the live file in a browser, run the checker again, and check the robots.txt report in Google Search Console.
- Review every 3 months and when a company confirms its start date (watch the Pulse box above).
Based on guidance from Digidai and PPC Land. The token is still a draft, so follow each company’s own documentation as it is published.
Free AI Training Opt Out Robots.txt Templates and Planner
Free for bloggers, publishers, agencies, brands and anyone managing websites for clients. No signup. Please credit Peplio and link to this page if you share them.Choose Allow or Block for 15 AI bots and the sheet writes your robots.txt lines. Includes a bot directory, the Indian study data and a review log.
Download ExcelReady rules for blogs, news sites, stores, SaaS, course creators and artists, with notes and WordPress steps.
Download PDFOne printable page: which bots train, which answer, which to never block, plus key dates.
Download PDFJournalists and bloggers: the Indian data and the three infographics on this page are free to use with credit and a link to Peplio’s AI training opt out robots.txt guide.
Shared Token vs Google-Extended vs Bing Tags vs llms.txt
| __usage_ai-training | Google-Extended | Bing meta tags | llms.txt | |
|---|---|---|---|---|
| Where | robots.txt | robots.txt | Page meta tag or X-Robots-Tag header | Separate file at /llms.txt |
| Covers | AI training, all supporting companies | Gemini training and Gemini Apps grounding | Bing AI training and AI grounding, per page | A guide to your key pages for AI tools |
| Example | User-Agent: __usage_ai-training | User-Agent: Google-Extended | <meta name="Bingbot" content="ai-training:disallow"> | A markdown list of links |
| Affects rankings? | No | No | No | No |
| Live? | From Feb 2027 (Microsoft), early 2027 (Google) | Yes, since Sep 2023 | From Feb 1, 2027 | Read by some AI tools |
AI Training Opt Out Robots.txt Mistakes to Avoid
- Expect
User-agent: *to cover AI training - Block OAI-SearchBot or PerplexityBot to stop training
- Block Googlebot or Bingbot to avoid AI answers
- Delete GPTBot and ClaudeBot rules before support is live
- Name
__usage_ai-trainingexactly - Decide Google-Extended on purpose
- Keep dated copies of your robots.txt
- Re-check after every theme, plugin or SEO plugin change
Most Indian sites do not need to opt out of AI training. They need to stop blocking AI search by mistake.
For a small business or blogger, being known by AI tools is a new front door, so I would say yes to training clearly and keep every AI search bot open. If you sell original courses, research or art, opt out the folders you sell and share the rest. Either way, the study shows the bigger risk is the 11 sites that block ChatGPT search while trying to stop training. Write one clear line on purpose, and check it again when Google and OpenAI switch on.
Who Honours the AI Training Opt Out Token (Tracker)
I update this table every Monday. Seen a company confirm a date? Share the source and get credited.| Company | Status | Start date | Source |
|---|---|---|---|
| Microsoft (Bing) | Committed | February 1, 2027 | PPC Land |
| Committed | Early 2027 | Relevant Audience | |
| OpenAI | Committed | “Within the next few months” | The Back Room Tech |
| Anthropic | Building support | No date yet | Relevant Audience |
| Meta, Apple, Amazon, ByteDance | Not announced | None | PPC Land |
Whatever you choose for training, check that AI search can still read and quote your key pages.
- November 2, 2026: Hub launched with the Indian AI crawler data, a robots.txt checker, a builder with site-type suggestions, 6 templates, the support tracker, a branded Excel planner, 2 PDF guides and 3 free infographics. Added Bing’s new AI Training and AI Grounding controls and dates.
Peplio’s comic stories teach SEO and AI search through a bakery that learns everything the hard way. Start reading the digital marketing comic stories.
- The AI training opt out in robots.txt is
User-Agent: __usage_ai-trainingplusDisallow: /, announced October 30, 2026. - Microsoft honours it from February 1, 2027, Google in early 2027, OpenAI within months, and Anthropic is building support.
- It does not stop crawling and does not change Google or Bing rankings.
- For Google, a token opt-out counts as a Google-Extended block, which can also affect Gemini Apps grounding.
- Peplio’s study found 0 of 230 Indian sites use it yet, and 11 block ChatGPT search by mistake.
Will blocking AI training hurt my SEO?
No, not your Google or Bing rankings. Blocking AI search bots is what hurts AI visibility. Learn how AI visibility works in our generative engine optimization guide.How do I get cited by AI tools instead?
Keep AI search bots open and write clear, quotable answers. See how to get cited by Perplexity.Do I still need an llms.txt file?
It is optional and separate from your training choice. See what an llms.txt file is.FAQ About the AI Training Opt Out in Robots.txt
What is __usage_ai-training?
It is a shared robots.txt token that Google, Microsoft, OpenAI and Anthropic agreed to honour on October 30, 2026. A group with User-Agent: __usage_ai-training and Disallow: / tells them not to use your pages to train AI models.When does the AI training opt out in robots.txt start working?
Microsoft starts on February 1, 2027 and Google in early 2027. OpenAI says within the next few months, and Anthropic has started building support. Adding it now means you are ready on day one.Does the AI training opt out affect my Google rankings?
No. It is a usage preference, not a crawling rule, and Microsoft and Google both say normal search rankings are not affected.Does User-agent: * cover AI training?
No. The draft says a wildcard group must not be read as the training token. You have to name __usage_ai-training exactly.Should I still block GPTBot and ClaudeBot?
If you want to opt out, yes for now. Keep those rules until OpenAI and Anthropic confirm their support is live, then you can rely on the shared token.How many Indian websites use the AI training opt out token?
None yet. Peplio checked 300 well-known Indian websites on November 1, 2026. Of the 230 with a readable robots.txt, 0 used the token, while 39 blocked at least one AI crawler by name.Fact check: the token syntax, the October 30, 2026 announcement and the four backers are confirmed by PPC Land, Relevant Audience, ShiftDelete and The Back Room Tech. Microsoft’s dates come from Bing’s announcement as reported by PPC Land and The Back Room Tech. Google’s Google-Extended treatment is from Google’s post as quoted by Relevant Audience and Search Engine Roundtable. The Indian figures are Peplio’s own data from robots.txt files read on November 1, 2026.
All data as of November 2, 2026. Peplio is not affiliated with Google, Microsoft, OpenAI or Anthropic. The token is still a draft and can change, so check each company’s documentation before relying on it. This is not legal advice about your content rights.